This post explains what a Temporal workflow is and how the model works in Go. Then it shows how Temporal makes microservices reliable with retries, backpressure and durable state. You will also run a real Temporal and Golang example and see why Temporal can restart a function from the beginning without repeating finished work.
What is a Temporal workflow?
A Temporal workflow is ordinary code, in Go or another supported SDK, that Temporal runs durably. Temporal records each step in an event history. So if a worker or service crashes, the workflow replays that history and resumes where it stopped. Side effects such as API calls run as activities, which Temporal retries under the timeouts and retry policy you set.
For the full model, see Temporal’s workflow documentation. Spiral Scout is a Temporal partner, and we build on it for clients through our Temporal consulting and development work. The rest of this post walks through one small, complete example.
Microservices Architecture With Temporal
An earlier Spiral Scout post on concurrency and parallelism in Golang showed how to speed up Go code. It split computations by algorithm and by data so they could run in parallel. Even so, one application still runs on one host or container, and the code cannot exceed that machine’s CPU and RAM limits.
You can lift those limits with a bigger machine, but that always raises costs. The program may sit idle much of the time, and you still pay for expensive hardware during those quiet periods.
A better option is a microservices architecture. When you run the same application on several hosts and spread the load across the instances, that is load balancing. With microservices, developers can add hosts and start new instances of an application on demand.
Four principles for microservices
Microservices should follow four common principles. First, a microservice should be small: simple enough for one person to understand. Second, it should be focused on one business task and solve it in a generic way, so another part of the system can reuse it.
Third, it should be loosely coupled. It should not require any changes, it should relate to external APIs, and it should have no database relations or backdoors. Finally, it should be highly cohesive and hold every method its business task needs. No other microservice should perform the same activity unless it works in a completely different way.
The earlier post used a simple test task: an application that calculates metrics for many figures. The figures were parallelepipeds, and for each one we needed the base square and the volume. It was not a real-world case, but it shows the basic principles clearly.
Applying the principles above, we can split the same task into three microservices. The Square Microservice computes the square, and the Volume Microservice computes the volume. Then the Parallelepiped Microservice splits all the parallelepipeds into batches and sends the batches to the Square and Volume Microservices in parallel.
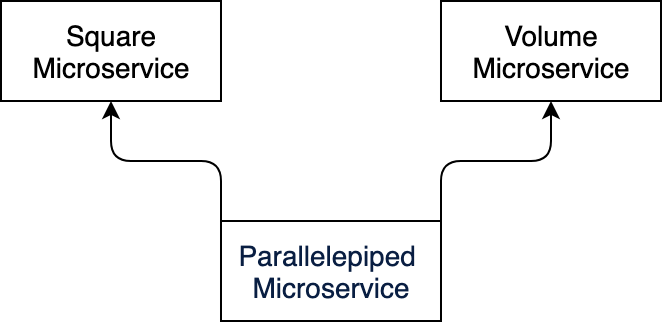
The Parallelepiped Microservice depends on the Square and Volume Microservices, so it is less generic than those two. Dependencies between microservices should follow the same rule as dependencies between components: they should form a Directed Acyclic Graph (DAG).
Microservices Communication
The Parallelepiped Microservice has to call the Square and Volume Microservices, which run on different hosts. So it needs a Remote Procedure Call (RPC) technique. Standard synchronous transports include HTTP and gRPC (Google RPC), and asynchronous options include MQ (Message Queues).
To make those calls, the Parallelepiped Service must know the IP addresses of the Square and Volume Services. It also has to account for many possible instances of each service. As a result, we need one more component: Load Balancing across the instances, plus Service Discovery to find the right service addresses.
The most common approach gives the Parallelepiped Service domain names such as volume.microservice and square.microservice. Service Discovery and Load Balancing then live inside the domain name system service (DNS). In turn, the DNS resolves each name to the IP of a concrete service instance (for example, 192.168.1.112) and balances the load:

Distributed System Problems
So far, so good. The Parallelepiped Microservice knows the domain names of the Volume and Square Microservices. It accepts a large number of parallelepipeds with their dimensions, splits them into batches, and sends them out to compute volume and square in parallel.
Problems start because the services are spread across a network. The network may go down, the host computers may stop or fail, and the Parallelepiped Service itself may fail. That is why you need to predict edge cases and plan four safeguards.
First, a retry mechanism repeats calls that a network failure or a target service failure interrupted. Second, backpressure limits the load on the target services (the Square and Volume Microservices). Third, the Parallelepiped Service must persist the state of the process (the workflow). Finally, you need timeout management.
If you use only known transports such as HTTP, gRPC or MQ, you must build all those fail-safes inside each microservice, for each transport. However, the number of services can be large, and so can the number of transports. Keeping all of that consistent becomes a real pain. Even then, in most cases you still cannot guarantee that the Parallelepiped Service will finish its job.
Worse, all that extra code breaks the microservice principles listed at the start of this post. The services grow, they drift away from their main business function, and they lose cohesion, because any service could now solve the same problems as the next one.
Why Microservices Need a Workflow Engine
Retries, backpressure and state persistence are generic requirements. They have nothing specific to do with the parallelepiped calculation. Instead, they belong to a general group of long-running microservice communications called microservice workflows. A separate service that provides all these features solves this class of problem far more efficiently.
You can choose from many engines, as this curated list on GitHub shows. As a software development company, we chose the Temporal engine. It is a microservice orchestration platform written in Go, and it runs as a separate set of services. You can find its official site, with documentation and FAQs, at https://temporal.io/. Beyond using Temporal in our own software development, Spiral Scout is a Temporal partner and worked with the Temporal team on its PHP integration.
This workflow engine works at the transport level. It provides service discovery and load balancing, and it resolves the stability and reliability problems that come with a distributed microservice architecture. It also handles retries and backpressure, which makes workflow execution very reliable.
Temporal Workflow Example and Diagram
Here is how Temporal works in practice. The diagram below shows how the example microservices at Spiral Scout connect through Temporal:

The Temporal service group has three parts. It includes the Temporal service, a persistence layer (Cassandra or PostgreSQL), and the TemporalUI service for visual management of workflows in a browser. Locally, you can start it with a simple docker-compose file:
https://github.com/guntenbein/temporal_microservices/blob/main/docker-compose.yml
Repository Structure
This repository shows how we use the Temporal workflow engine to orchestrate the Parallelepiped Microservices system:
https://github.com/guntenbein/temporal_microservices
The repository holds three microservices: Parallelepiped Workflow, Square and Volume. Usually every microservice has its own repository, but that is not a strict rule. What matters is that developers isolate each service’s code. You can do that inside one repository, and it works well for small microservices that share a repository but deploy and run separately.
The domain folder contains the services, activities and workflow for each microservice. Next, the cmd folder holds the main functions that run the Temporal workers and register the activities and workflows. Meanwhile, the controller folder contains the code that starts the workflow over HTTP. You could easily split the repository into three microservice repositories and move the starter into its own repository when needed.
In practice, we always separate domains inside one repository so they share no common service code. That lets us move a domain from one microservice to another quickly.
Also note the common code in the domain folder. Developers often create a separate repository for it, named go-workflows for example. They put the clean shared code there with its tests, so any microservice can reuse it.
Activities
Every service uses the Temporal API, built on gRPC protocol buffers, as its transport. When a service offers functionality for a Temporal workflow to use, it declares and registers an activity. An activity is a function that takes a context as its first argument. For example, the activity that calculates the square looks like this:
func (s Service) CalculateRectangleSquare(ctx context.Context, req CalculateRectangleSquareRequest) (resp CalculateRectangleSquareResponse, err error) {
The activity also includes code that sends heartbeats to Temporal to report that it is still alive:
					heartbeat := domain.StartHeartbeat(ctx, temporal_microservices.HeartbeatIntervalSec)
	defer heartbeat.Stop()
The rest is plain business code for the square calculation.
Workers
Each microservice starts a Temporal worker and then registers its activities with that worker:
worker.RegisterActivity(square.Service{}.CalculateRectangleSquare)
Worker options set how many activities can run in parallel, which is how the worker handles backpressure. Then you declare the worker for a specific queue:
worker := worker.New(temporalClient, temporal_microservices.SquareActivityQueue, workerOptions)
This way, Temporal limits the capacity for each type of functionality, meaning the activities and workflows registered for that worker.
The Temporal Workflow Code
The Parallelepiped Microservice declares its own workflow:
func CalculateParallelepipedWorkflow(ctx workflow.Context, req CalculateParallelepipedWorkflowRequest) (resp CalculateParallelepipedWorkflowResponse, err error) {
if len(req.Parallelepipeds) == 0 {
err = BusinessError{"there are no figures to process"}
return
}
if isIDsRepeat(req.Parallelepipeds) {
err = BusinessError{"the ids of the figures in the input should be unique"}
return
}
if req.BatchSize <= 0 {
err = BusinessError{"makeBatch size cannot be less or equal to zero"}
return
}
batchCount := batchCount(len(req.Parallelepipeds), req.BatchSize)
selector := workflow.NewNamedSelector(ctx, "select-parallelepiped-batches")
var errOneBatch error
cancelCtx, cancelHandler := workflow.WithCancel(ctx)
count := 0
squareMap := make(map[string]float64)
volumeMap := make(map[string]float64)
for i := 0; i < batchCount; i++ {
batch := makeBatch(req.Parallelepipeds, i, req.BatchSize)
future := processSquareAsync(cancelCtx, batch)
selector.AddFuture(future, func(f workflow.Future) {
respSquare := square.CalculateRectangleSquareResponse{}
if err := f.Get(cancelCtx, &respSquare); err != nil {
cancelHandler()
errOneBatch = err
} else {
copyResult(squareMap, respSquare.Squares)
}
})
count++
future = processVolumeAsync(cancelCtx, batch)
selector.AddFuture(future, func(f workflow.Future) {
respVolume := volume.CalculateParallelepipedVolumeResponse{}
if err := f.Get(cancelCtx, &respVolume); err != nil {
cancelHandler()
errOneBatch = err
} else {
copyResult(volumeMap, respVolume.Volumes)
}
})
count++
}
// wait until everything processed
for i := 0; i < count; i++ {
selector.Select(ctx)
if errOneBatch != nil {
return CalculateParallelepipedWorkflowResponse{}, errOneBatch
}
}
// map the output
var outputFigures = make([]Parallelepiped, 0, len(req.Parallelepipeds))
for _, p := range req.Parallelepipeds {
outputP := p
outputP.BaseSquare = squareMap[p.ID]
outputP.Volume = volumeMap[p.ID]
outputFigures = append(outputFigures, outputP)
}
return CalculateParallelepipedWorkflowResponse{Parallelepipeds: outputFigures}, nil
}
The workflow takes the input array of parallelepipeds and splits it into batches of the size set in the input. Then it sends each batch to the square activity:
					func processSquareAsync(cancelCtx workflow.Context, batch []Parallelepiped) workflow.Future {
	future, settable := workflow.NewFuture(cancelCtx)
	workflow.Go(cancelCtx, func(ctx workflow.Context) {
		ctx = withActivityOptions(ctx, temporal_microservices.SquareActivityQueue)
		respSquare := square.CalculateRectangleSquareResponse{}
		// map the domain structures
		dimensions, err := copySquareBatch(batch)
		if err != nil {
			settable.Set(nil, err)
			return
		}
		err = workflow.ExecuteActivity(ctx,
			square.RectangleSquareActivityName,
			square.CalculateRectangleSquareRequest{Rectangles: dimensions}).Get(ctx, &respSquare)
		settable.Set(respSquare, err)
	})
	return future
}
At the same time, it sends each batch to the volume activity in parallel:
					func processSquareAsync(cancelCtx workflow.Context, batch []Parallelepiped) workflow.Future {
	future, settable := workflow.NewFuture(cancelCtx)
	workflow.Go(cancelCtx, func(ctx workflow.Context) {
		ctx = withActivityOptions(ctx, temporal_microservices.SquareActivityQueue)
		respSquare := square.CalculateRectangleSquareResponse{}
		// map the domain structures
		dimensions, err := copySquareBatch(batch)
		if err != nil {
			settable.Set(nil, err)
			return
		}
		err = workflow.ExecuteActivity(ctx,
			square.RectangleSquareActivityName,
			square.CalculateRectangleSquareRequest{Rectangles: dimensions}).Get(ctx, &respSquare)
		settable.Set(respSquare, err)
	})
	return future
}
The Parallelepiped Microservice does not care where the activities run. It does not know the addresses of the Square and Volume services, and it relies on Temporal to know them. In our implementation, however, the activities use Request-Response structures, and those structures live in the Square and Volume Microservices:
					type Rectangle struct {
	ID     string
	Length float64
	Width  float64
}

type Service struct{}

type CalculateRectangleSquareRequest struct {
	Rectangles []Rectangle
}

type CalculateRectangleSquareResponse struct {
	Squares map[string]float64
}
As a result, the Parallelepiped Microservice code depends on the Square and Volume Microservices. That is useful, because the dependency shows which versions of the Square and Volume Microservices the Parallelepiped Workflow needs.
					type Rectangle struct {
	ID     string
	Length float64
	Width  float64
}

type Service struct{}

type CalculateRectangleSquareRequest struct {
	Rectangles []Rectangle
}

type CalculateRectangleSquareResponse struct {
	Squares map[string]float64
}
A separate worker inside the Parallelepiped Microservice registers the workflow:
worker.RegisterWorkflow(workflow.CalculateParallelepipedWorkflow)
Each activity runs with its own options. It goes to a dedicated Temporal queue and can have its own retry policy and timeouts:
					func withActivityOptions(ctx workflow.Context, queue string) workflow.Context {
	ao := workflow.ActivityOptions{
		TaskQueue:              queue,
		ScheduleToStartTimeout: 24 * time.Hour,
		StartToCloseTimeout:    24 * time.Hour,
		HeartbeatTimeout:       time.Second * 5,
		RetryPolicy: &temporal.RetryPolicy{
			InitialInterval:        time.Second,
			BackoffCoefficient:     2.0,
			MaximumInterval:        time.Minute * 5,
			NonRetryableErrorTypes: []string{"BusinessError"},
		},
	}
	ctxOut := workflow.WithActivityOptions(ctx, ao)
	return ctxOut
}
To run activities concurrently, Temporal workflows use Futures and Selectors. The process running the workflow may fail, but Temporal keeps working until it completes the workflow. In practice, the workflow code only defines the tasks for concurrent execution, and the Temporal server then runs the activities in parallel. That is why developers should not use goroutines and channels in workflow code. Instead, Temporal provides its own replacements for them.
Starting the Temporal Workflow
At this point Temporal has everything it needs to run the workflow and its activities. It still needs a start request and the input data. For that, a simple HTTP handler in the Parallelepiped Microservice receives the parallelepiped data and starts the workflow:
					func executeWorkflow(ctx context.Context, temporalClient client.Client, wReq workflow.CalculateParallelepipedWorkflowRequest) (output []workflow.Parallelepiped, err error) {
	workflowOptions := client.StartWorkflowOptions{
		TaskQueue: temporal_microservices.FigureWorkflowQueue,
	}
	workflowRun, err := temporalClient.ExecuteWorkflow(ctx, workflowOptions, workflow.CalculateParallelepipedWorkflow, wReq)
	if err != nil {
		return
	}
	workflowResp := workflow.CalculateParallelepipedWorkflowResponse{}
	err = workflowRun.Get(ctx, &workflowResp)
	if err != nil {
		return
	}
	return workflowResp.Parallelepipeds, nil
}
Note that the starter waits for the workflow to complete, so it runs the workflow synchronously:
err = workflowRun.Get(ctx, &workflowResp)
You can also start the workflow and immediately return HTTP 202 Accepted, which tells the caller the workflow has started but has not finished. This option suits long-running workflows better, because HTTP calls time out.
Running the Temporal Microservices Locally
$ git clone https://github.com/guntenbein/temporal_microservices.git
Next, start the Temporal services by running this command from the project root:
$ docker-compose up -d
Once the Temporal service is up, run the microservices one by one:
					$ go run cmd/microservice_square/main.go
$ go run cmd/microservice_volume/main.go
$ go run cmd/microservice_workflow/main.go
Then prepare the input data. JSON Generator is a handy site for this. Use the following snippet to generate the workflow input:
					{
  BatchSize: 200,
  Parallelepipeds:
    [
      '{{repeat(5000, 10000)}}',
      {
        ID: '{{objectId()}}',
        Length: '{{floating(0, 10000)}}',
        Width: '{{floating(0, 10000)}}',
        Height: '{{floating(0, 10000)}}'
      }
    ]
}
}'
After that, run the workflow with this command:
					$ curl --location --request POST 'localhost:8080' \
--header 'Content-Type: application/json' \
--data-raw '{
  "BatchSize": 3,
  "Parallelepipeds": [
    {
      "ID": "5fedcbf7901feb7213e84153",
      "Length": 7584.6668,
      "Width": 8551.7289,
      "Height": 7911.1765
    },
    {
      "ID": "5fedcbf755d18a8e807432d2",
      "Length": 9854.9176,
      "Width": 2333.052,
      "Height": 9977.8465
    },
    {
      "ID": "5fedcbf776f93aa072884a6e",
      "Length": 6186.1635,
      "Width": 7257.3111,
      "Height": 744.9772
    },
    {
      "ID": "5fedcbf7cab168b5fa23e0bf",
      "Length": 1487.9815,
      "Width": 6904.6383,
      "Height": 6917.9239
    },
    {
      "ID": "5fedcbf7f1d0f9b6c8d94478",
      "Length": 9579.1483,
      "Width": 3908.5532,
      "Height": 1622.9292
    },
    {
      "ID": "5fedcbf7fd6de933e37141c6",
      "Length": 6060.2393,
      "Width": 5232.1464,
      "Height": 5528.2147
    },
    {
      "ID": "5fedcbf7a27adeb782670e09",
      "Length": 7608.5178,
      "Width": 3490.3491,
      "Height": 6064.8596
    },
    {
      "ID": "5fedcbf74cc4c73c8bdb6652",
      "Length": 6061.7923,
      "Width": 8985.7511,
      "Height": 7535.418
    },
    {
      "ID": "5fedcbf7b89726935be95418",
      "Length": 8633.0144,
      "Width": 4433.371,
      "Height": 2310.1432
    },
    {
      "ID": "5fedcbf7b55873c13a3d09c6",
      "Length": 6324.4951,
      "Width": 2566.1975,
      "Height": 7536.6964
    }
  ]
}'
After a while, the response comes back with the square and volume for each figure:
					[
    {
        "ID": "5fedcbf7901feb7213e84153",
        "Length": 7584.6668,
        "Width": 8551.7289,
        "Height": 7911.1765,
        "BaseSquare": 64862014.27043052,
        "Volume": 513134843038.89453
    },
    {
        "ID": "5fedcbf755d18a8e807432d2",
        "Length": 9854.9176,
        "Width": 2333.052,
        "Height": 9977.8465,
        "BaseSquare": 22992035.216515202,
        "Volume": 229410998112.98294
    },
    {
        "ID": "5fedcbf776f93aa072884a6e",
        "Length": 6186.1635,
        "Width": 7257.3111,
        "Height": 744.9772,
        "BaseSquare": 44894913.034964845,
        "Volume": 33445686607.031612
    },
    {
        "ID": "5fedcbf7cab168b5fa23e0bf",
        "Length": 1487.9815,
        "Width": 6904.6383,
        "Height": 6917.9239,
        "BaseSquare": 10273974.05459145,
        "Volume": 71074570660.2381
    },
    {
        "ID": "5fedcbf7f1d0f9b6c8d94478",
        "Length": 9579.1483,
        "Width": 3908.5532,
        "Height": 1622.9292,
        "BaseSquare": 37440610.74123956,
        "Volume": 60763460437.79133
    },
    {
        "ID": "5fedcbf7fd6de933e37141c6",
        "Length": 6060.2393,
        "Width": 5232.1464,
        "Height": 5528.2147,
        "BaseSquare": 31708059.23663352,
        "Volume": 175288959180.42822
    },
    {
        "ID": "5fedcbf7a27adeb782670e09",
        "Length": 7608.5178,
        "Width": 3490.3491,
        "Height": 6064.8596,
        "BaseSquare": 26556383.255563978,
        "Volume": 161060735928.78644
    },
    {
        "ID": "5fedcbf74cc4c73c8bdb6652",
        "Length": 6061.7923,
        "Width": 8985.7511,
        "Height": 7535.418,
        "BaseSquare": 54469756.827696525,
        "Volume": 410452386055.04724
    },
    {
        "ID": "5fedcbf7b89726935be95418",
        "Length": 8633.0144,
        "Width": 4433.371,
        "Height": 2310.1432,
        "BaseSquare": 38273355.6835424,
        "Volume": 88416932373.51683
    },
    {
        "ID": "5fedcbf7b55873c13a3d09c6",
        "Length": 6324.4951,
        "Width": 2566.1975,
        "Height": 7536.6964,
        "BaseSquare": 16229903.514382252,
        "Volume": 122319855389.19206
    }
]
Open the Temporal UI to see the result of the workflow execution:
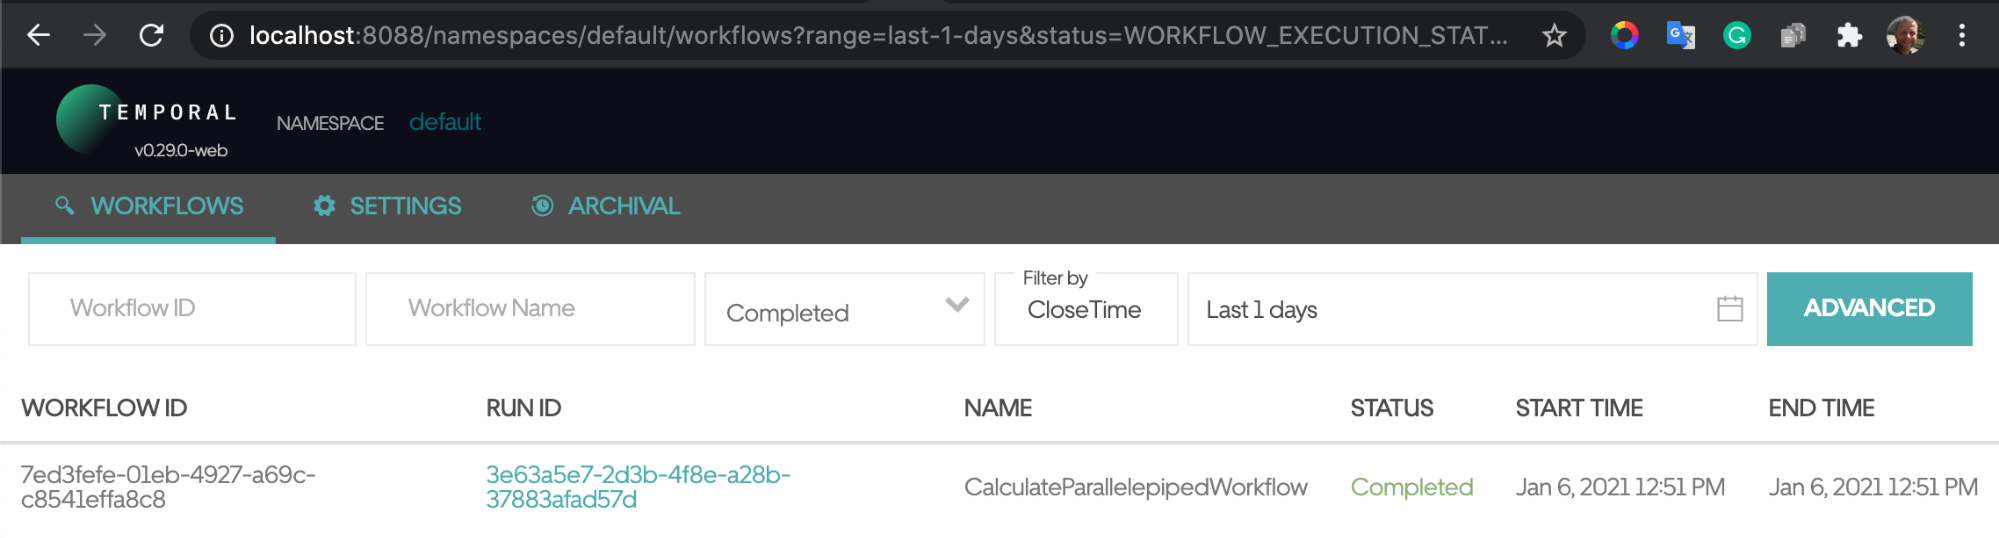
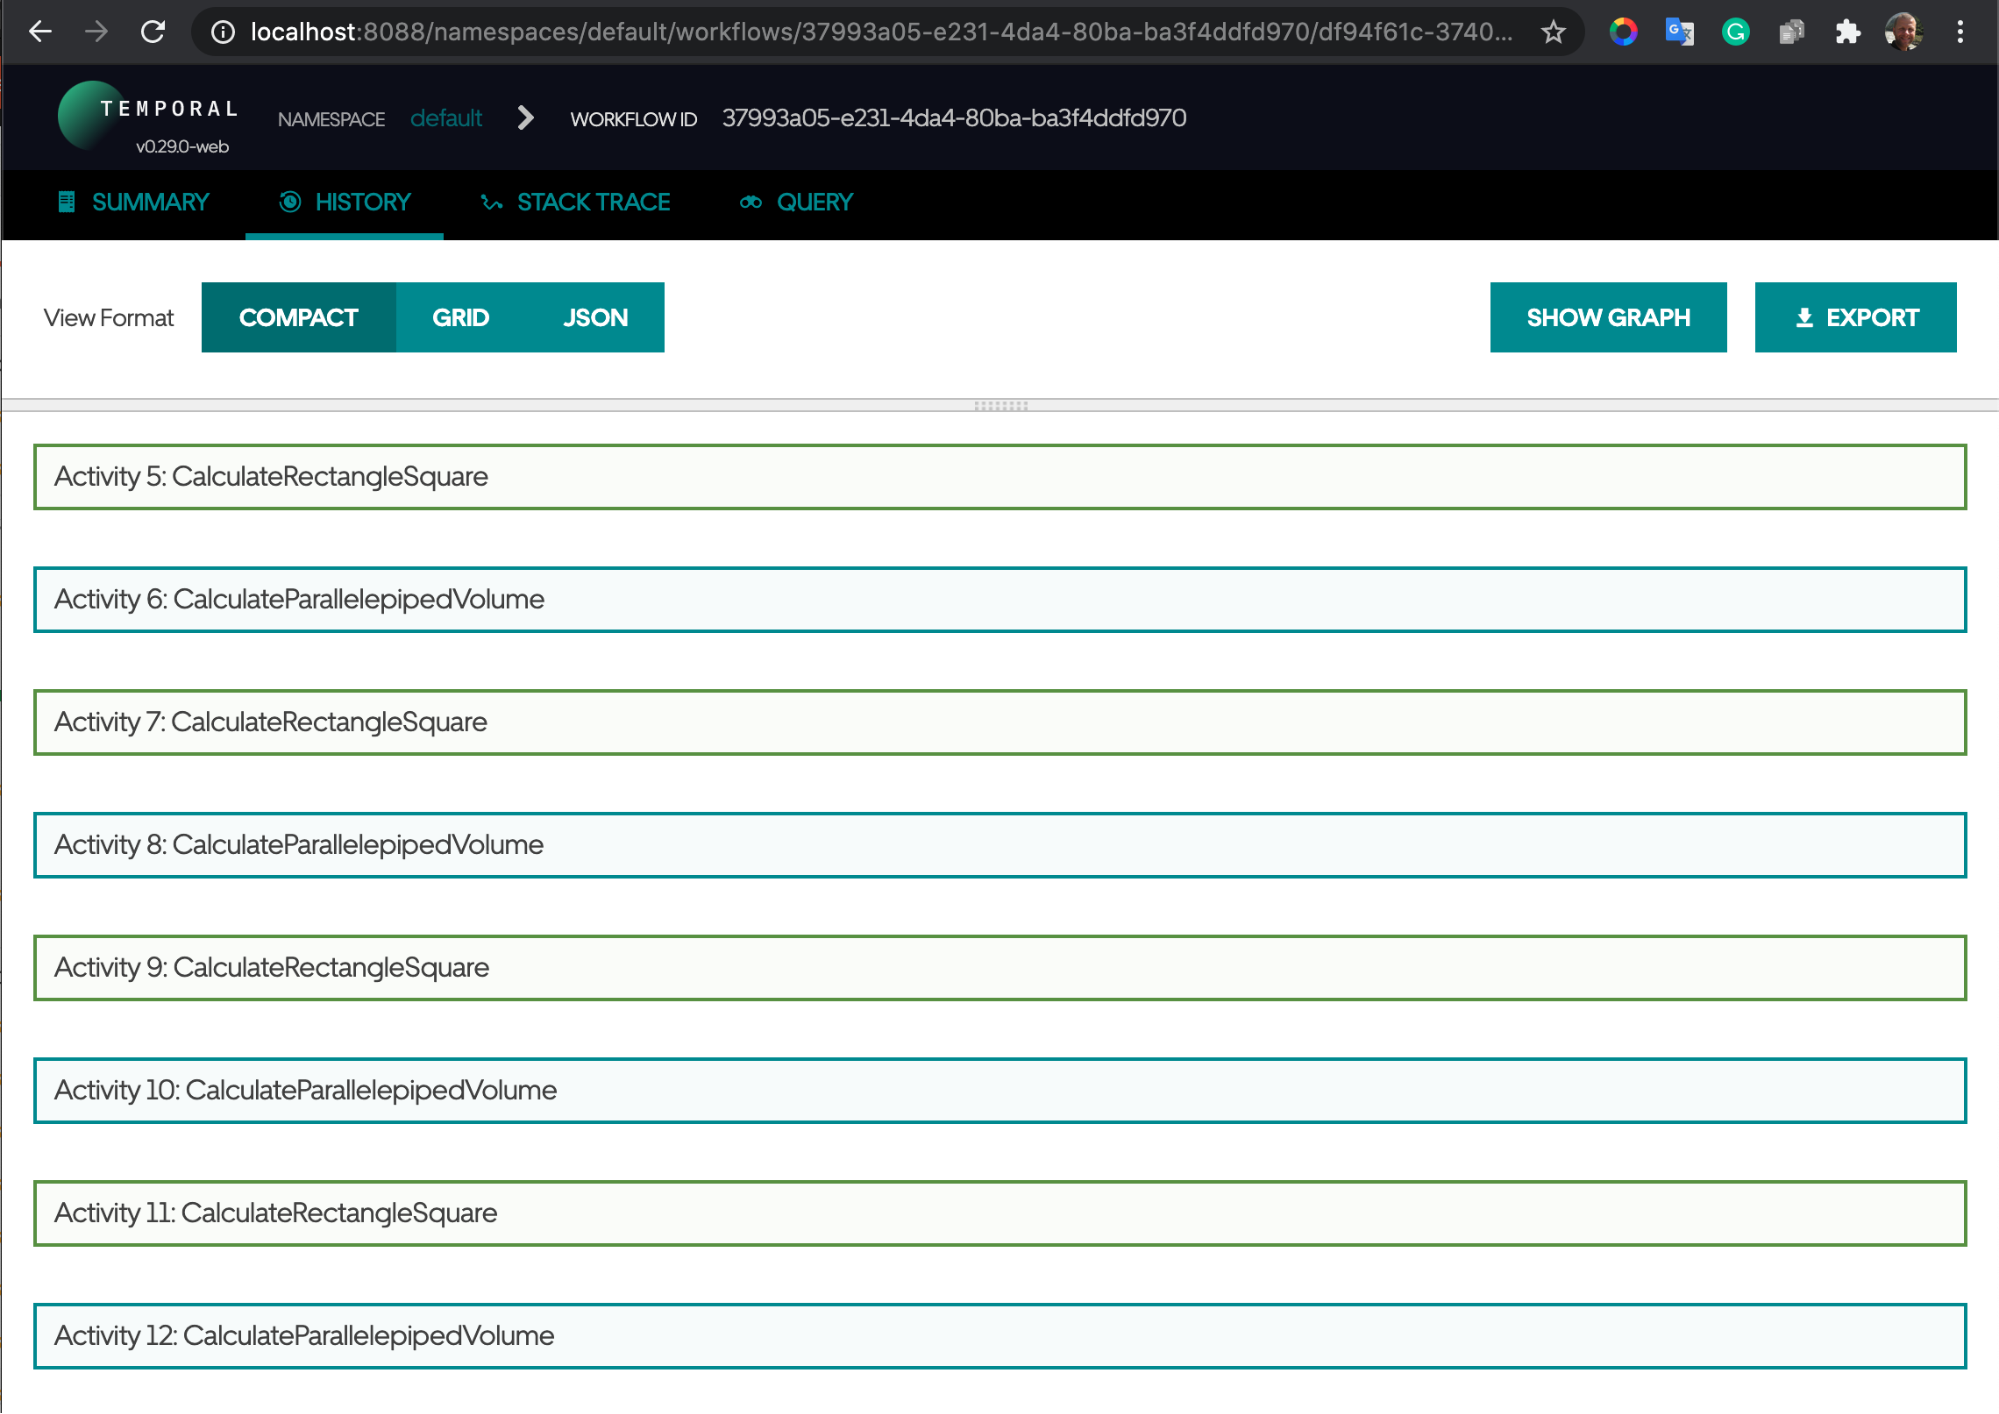
The UI shows that Temporal split the input payload into batches and ran the Square and Volume activities in parallel.
How the Temporal Workflow Handles Failures
When One of the Services Does Not Run
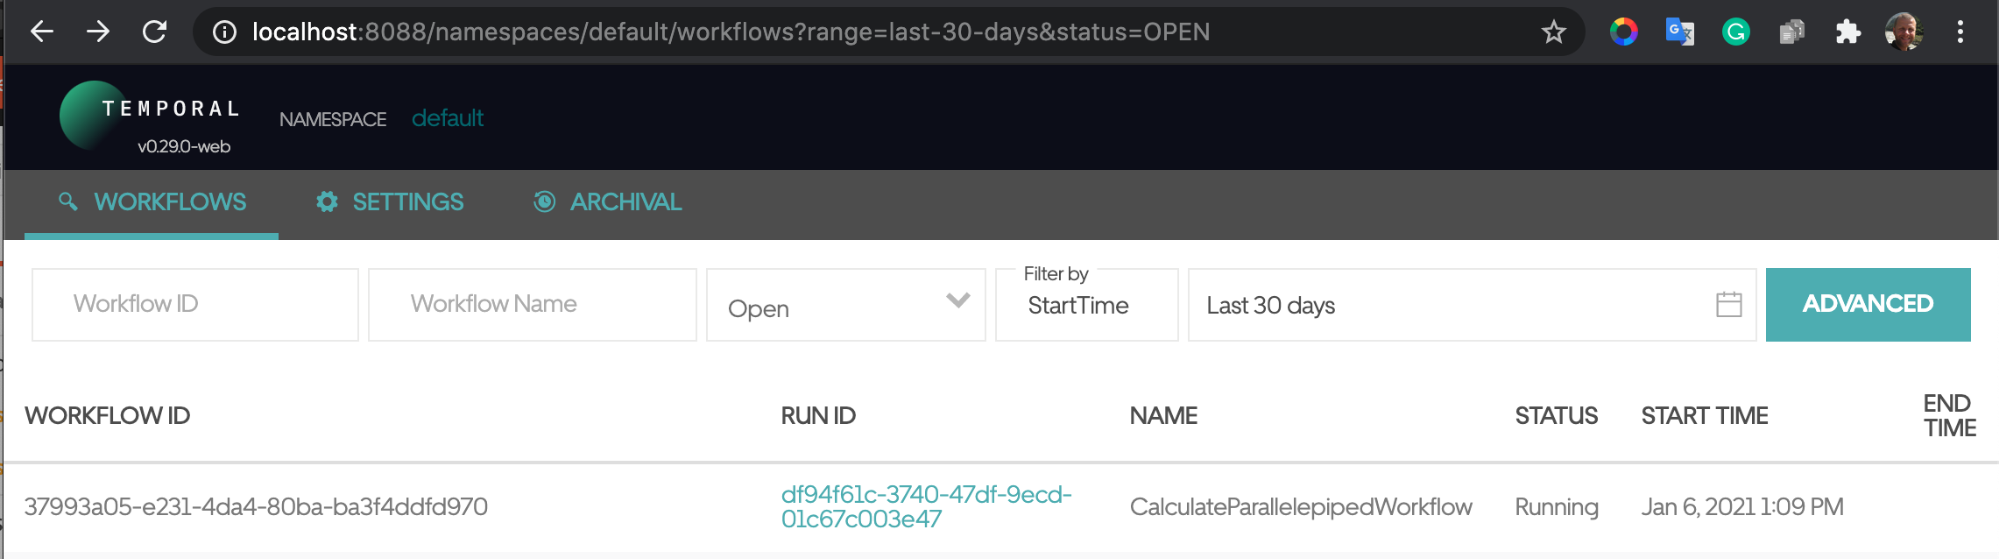
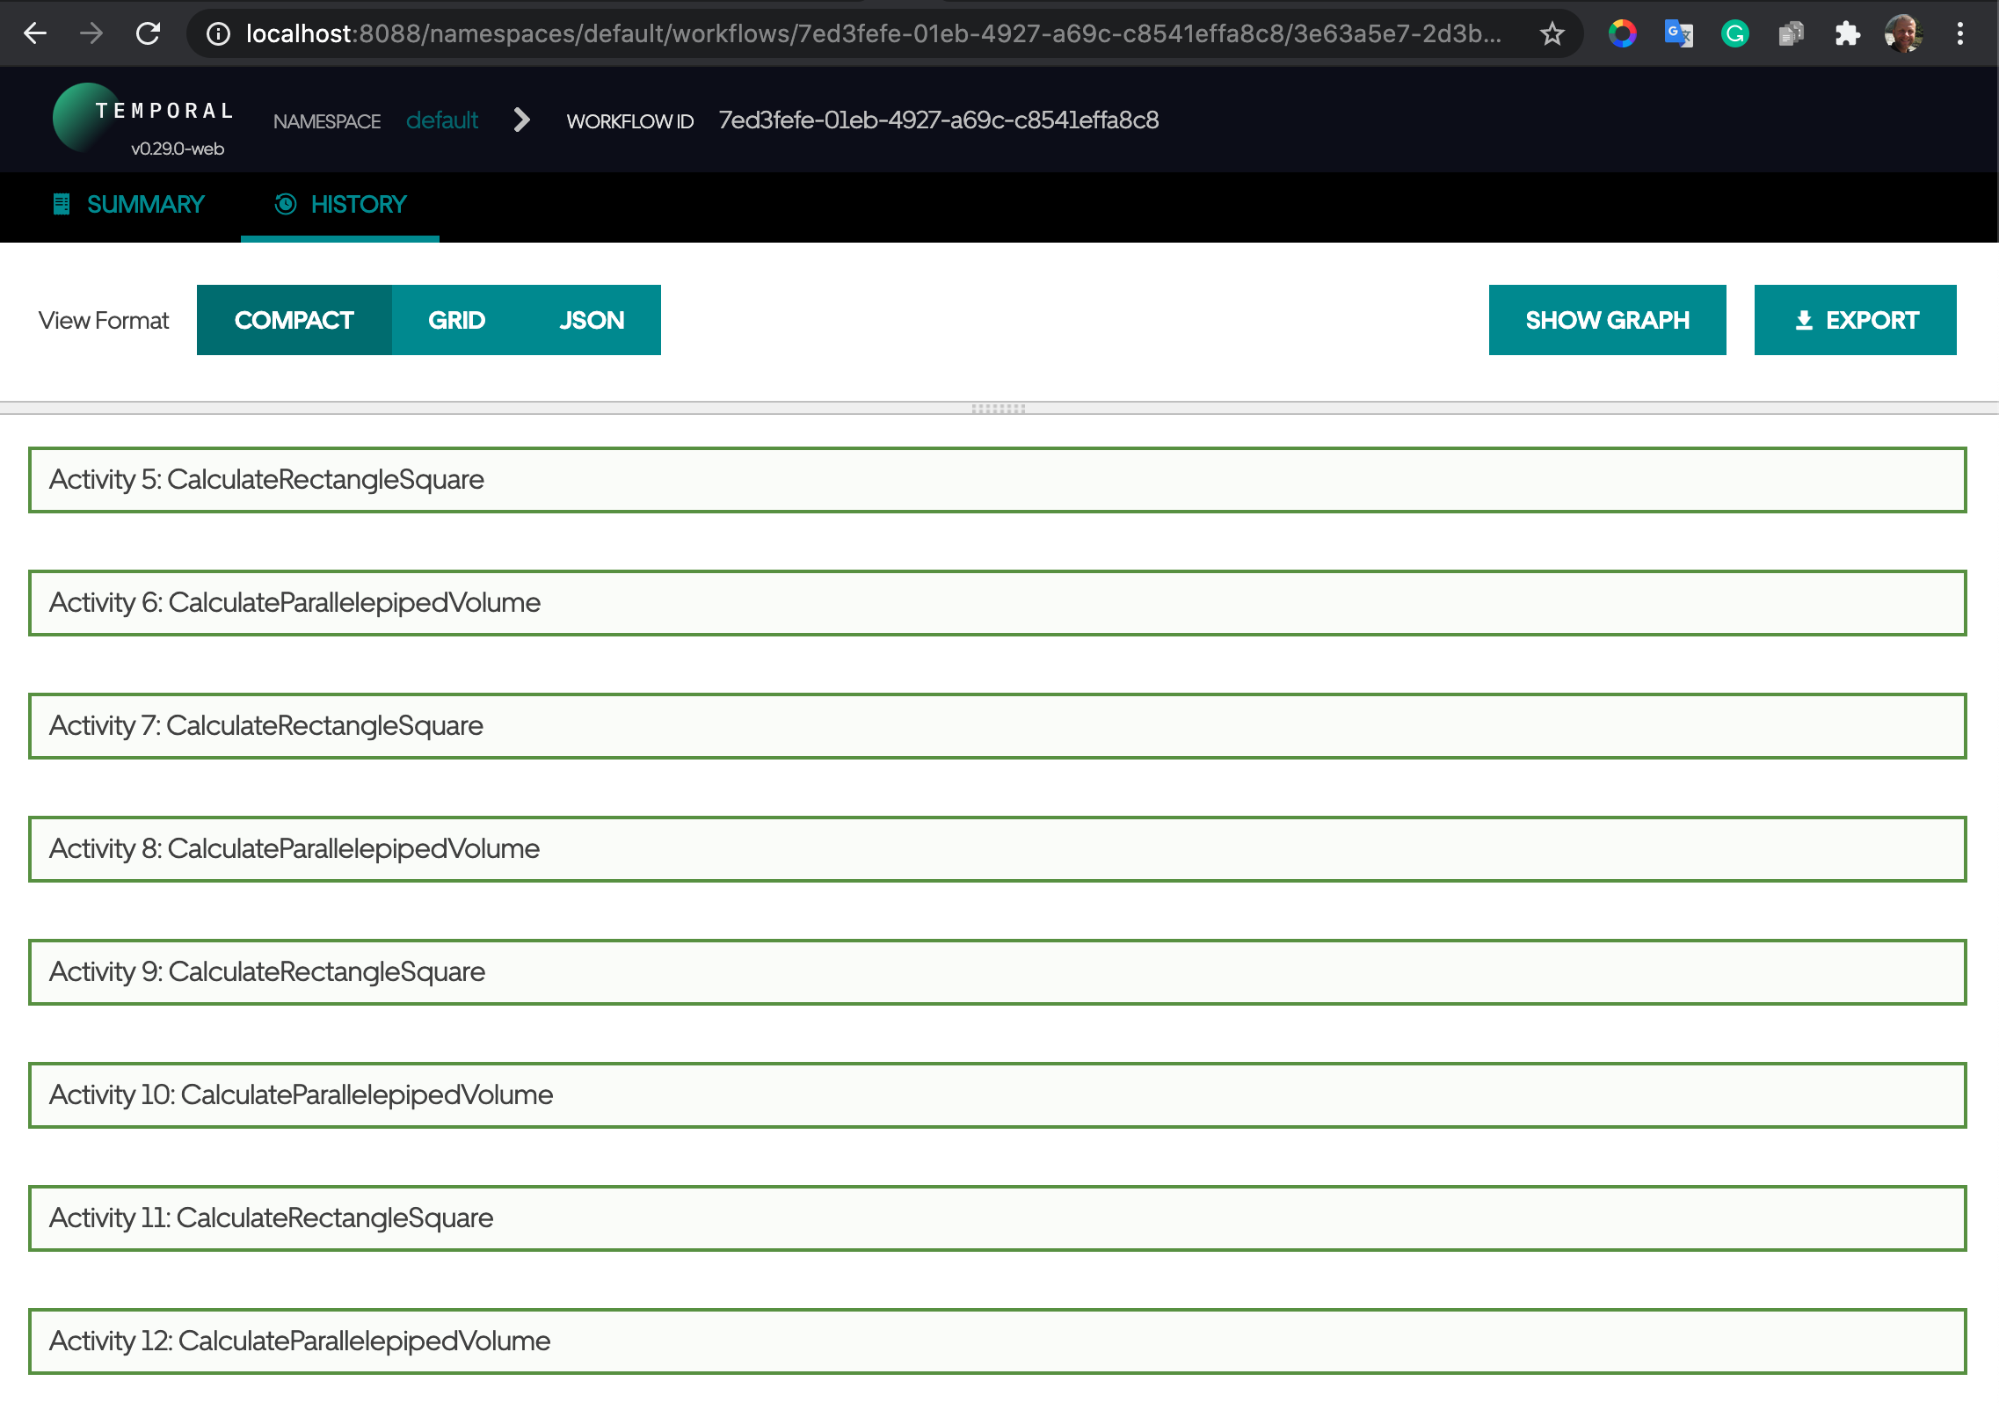
Now run the same process, but stop the Volume Microservice first. The HTTP request stays idle, the Temporal workflow stays in the running state, and the Volume activities wait as pending:
Once you restart the Volume Microservice, however, the workflow completes successfully.
When One of the Services Returns an Internal Error
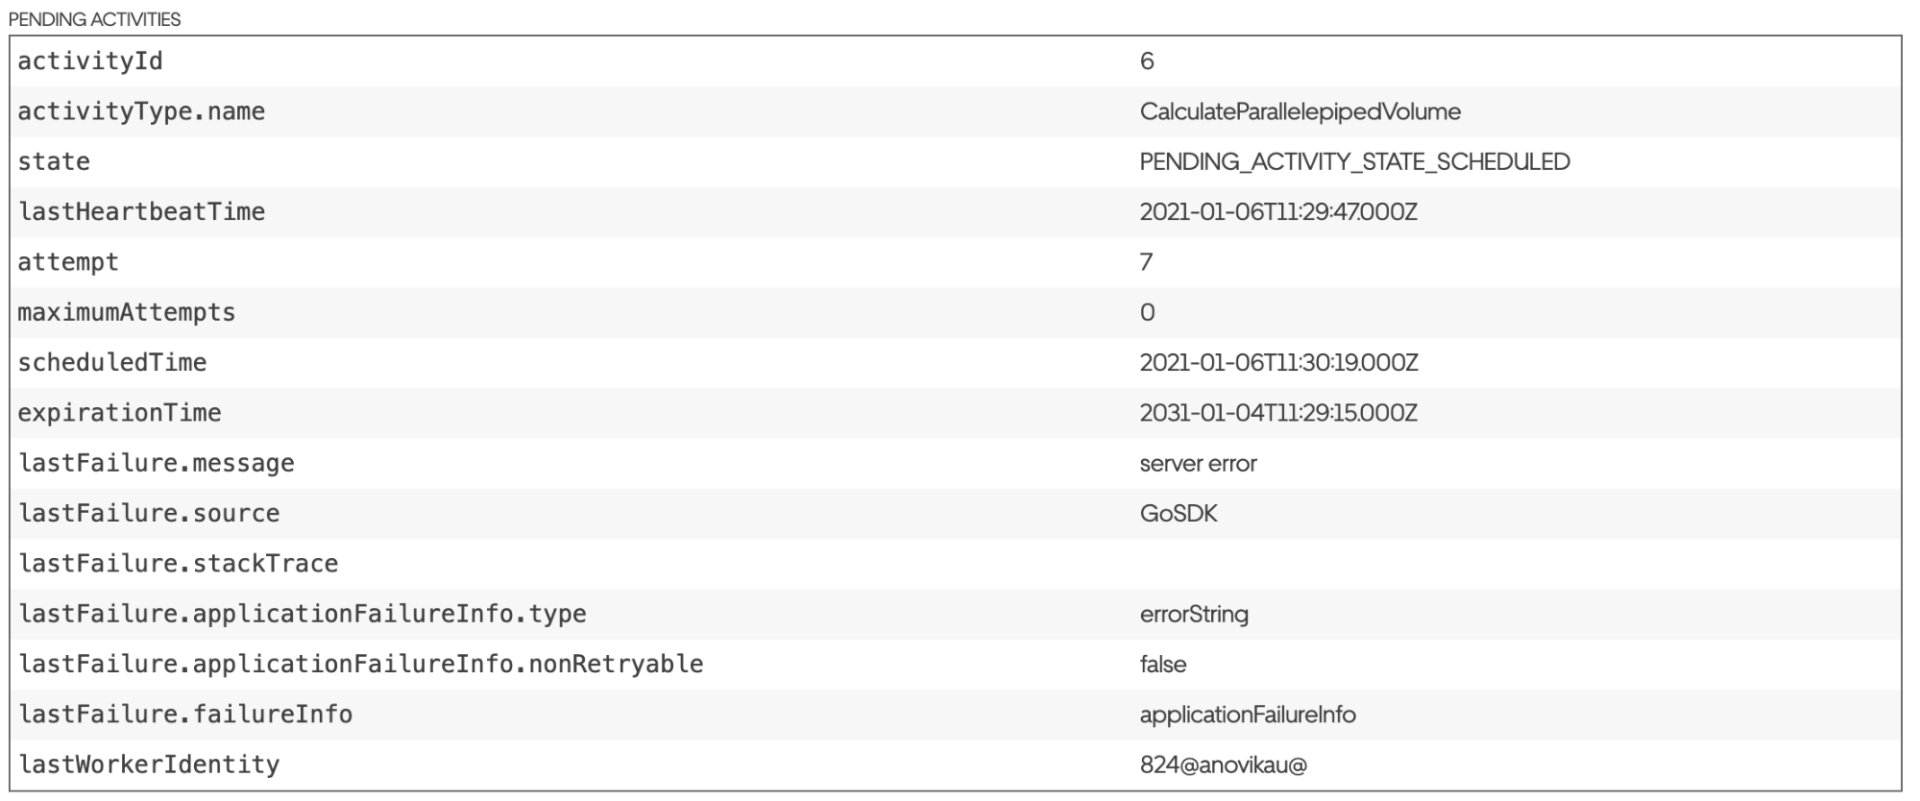
Next, add a line that returns an error inside the CalculateParallelepipedVolume method in the volume service:
return resp, errors.New("server error")
Now the service always returns this error. When you start the workflow, the HTTP call idles and the workflow stays in the running state, with this pending activities notice:
Then remove the error and restart the Volume service, and the workflow completes. It takes a while, because the retry policy uses exponential backoff.
Unit Testing Temporal Workflows
For tests, Temporal provides a solid framework that checks workflow code without running any real activities. You can mock activities on the fly, with no code generation. Here is an example test:
for i := 0; i < count; i++ {
Run the tests with the -race flag, and you can also confirm there are no data races:
$ go test -v -race ./…
At first glance, this line looks like it could cause a race:
if err := f.Get(cancelCtx, &respSquare); err != nil {
It does not, and running the tests with the -race and -count flags proves it:
$ go test -v -race -count 100 ./…
The concern comes from the activities running in parallel. However, the code fetches their results sequentially here:
for i := 0; i < count; i++ {
Conclusions: What Temporal Does Well
The Temporal engine gives you full control over workflows, including retries, timeouts, backpressure and parallel execution of activities. You can write workflows in many programming languages, with checks, conditions and execution sequences. Here are its key benefits.
First, the engine guarantees workflow completion even if the services running the workflow and its activities fail. The Temporal services, including the database, can run as a cluster and are fault-tolerant too. Second, the TemporalUI gives you a convenient way to view and control workflows.
Third, a unit test suite makes it easy to write tests for workflows. You can also connect Elasticsearch for more advanced search inside workflow data. Client SDK coverage has grown well beyond Java and Go since this post first appeared. Temporal now lists eight officially supported SDKs, including PHP, one Spiral Scout built for them directly.
Finally, Temporal fits any process made of many long-running steps, and it handles large portions of input data. One caveat: services that stream data may not be a good fit.
In short, a Temporal workflow gives you a reliable, fault-tolerant way to manage a wide range of long-running processes by orchestrating microservices. If you are planning a system like this, our Temporal consulting team can review your design before you build.
Building AI Agents With Temporal (Replay 2024)
Production AI agents need more than clever prompting. They also need durable execution, which is exactly what a Temporal workflow provides. In this series, we cover the practical side of building stateful, long-running agents.
Watch the first session below, and explore the full playlist here to see how we use Temporal in agent systems. The sessions cover LLM provider flakiness, complex reasoning chains, and AI workflows that pick up where they left off when a service fails, without losing a transaction. For the newest features, read what Replay 2026 changes for agents on Temporal, or see how we build AI agents on Temporal for clients.